Robot Foundation Models Are Not Black Boxes
Cicero Campelo, CISSP
October 14, 2026 · 12 min read
Part of our guide to AI for startups.
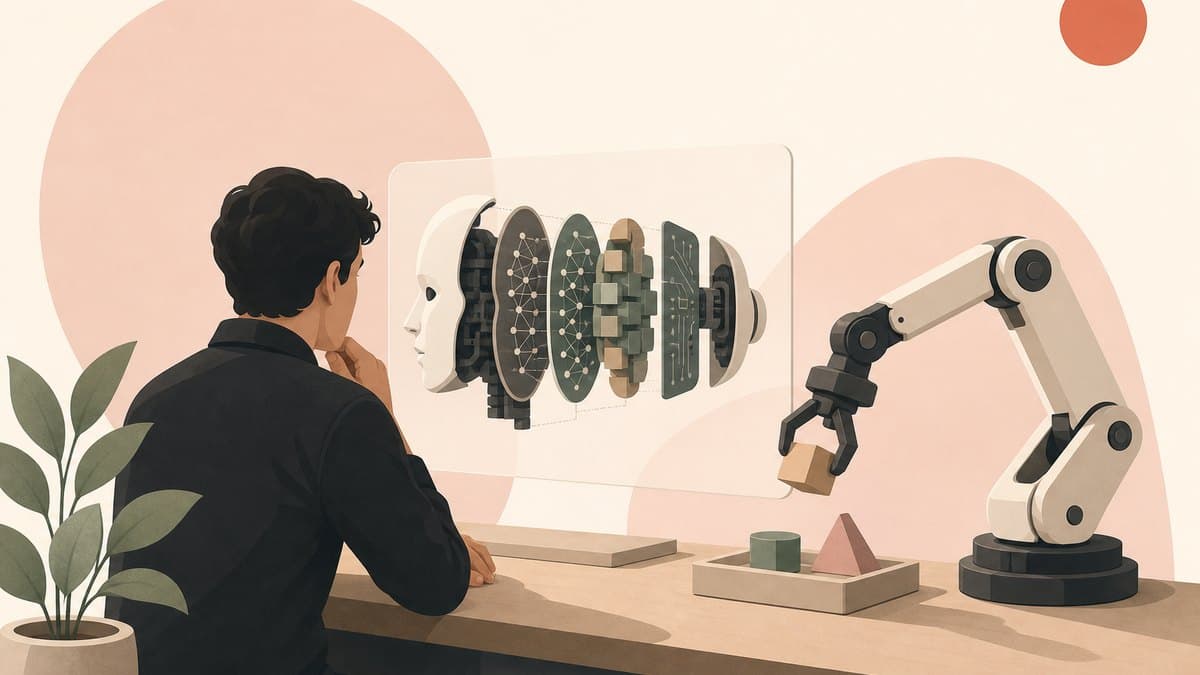
Table of contents
A robot foundation model is one learned model that takes an open-ended instruction in language, looks at what the robot's sensors see, and outputs the actions that move the machine. It replaces the modular stack robotics ran on for decades, where perception, planning, and control were three separate systems you tuned by hand for one machine doing one task in one room.
That swap is the whole reason robotics suddenly looks like a market instead of a research field. It also comes with a bill. The classical stack was explicit: kinematics, dynamics, and control were written down, so when the arm did something strange you could trace which model was wrong. A learned policy gives you generality and hands you back an object nobody can read.
The useful news, and the reason this is worth your afternoon, is that the second half of that sentence is less true than it was a year ago. The first framework for interpreting and steering these models through their own internal representations came out of a Berkeley lab, and what it found is that the inside of a robot foundation model is legible enough to grab. That changes what you should be asking the company that sells you the model.
What a robot foundation model actually is
Two families get named most often, and the workshop's call for papers names both. Vision-language-action models, usually shortened to VLAs, start from a pretrained vision-language model and learn to emit actions. World action models predict how the world changes when an action is taken, and act through that prediction. The call for papers for the robot foundation model safety workshop at the 2026 Conference on Robot Learning describes both as increasingly capable of accepting open-ended language instructions and outputting physical actions, with billions of dollars racing them into homes, warehouses, and streets.
What makes this a foundation model rather than a policy is the same thing that makes a language model a foundation model: it is pretrained broadly, and you adapt it rather than start from zero. That is why the model layer in robotics is now something you buy rather than something you spend years building, which is the shift the physical AI category is named after, and why the harder questions for a robotics company have moved to the cost structure of deployment and to where the training data comes from.
The part founders skip is what was given up in the trade. The research framing is blunt about it: methods for interpreting and steering these models fall well short of what classical robotics pipelines offered, because those pipelines were grounded in explicit models of kinematics, dynamics, and control. You did not lose a nice-to-have. You lost the explanation.
The inside is more legible than the demo suggests
Bear Häon, now an AI research scientist on the robotics team at Axon, did his graduate work at UC Berkeley in the lab of professor Claire Tomlin. With Kaylene Stocking, Ian Chuang, and Tomlin, he published Mechanistic Interpretability for Steering Vision-Language-Action Models at the 2025 Conference on Robot Learning. Speaking on YC's Root Access, he framed the question the paper set out to answer. The AI safety field had spent roughly a decade building interpretability, alignment, and control techniques for systems that think and at most act digitally, and he put the open question this way: "can we take those techniques and apply them to create concrete safety outcomes for systems that both think and physically act".
The method is easier to follow than the name suggests. Inside every transformer layer of the model sit feed-forward networks. The paper projects the activations of those networks onto the model's own token embedding basis, which is effectively the vocabulary the model understands. What comes back is close to a dictionary: for each feed-forward block, the concepts it responds to most strongly. Those blocks can then be clustered by concept, grouping the ones that carry ideas like fast, slow, or cautious. In the forward pass you amplify a cluster, and the behavior moves.
The demonstration is the part worth picturing. Give the robot the same natural language command twice, with one concept cluster turned down and then turned up, and as Häon describes it, "the robot is achieving the task in a much higher or lower action space because of this very direct control". The command did not change. The internals did.
Three details from the paper matter commercially. The steering happens at inference, with no fine-tuning, no reward signal, and no environment interaction. The method identifies sparse semantic directions, speed and direction among them, that the paper shows are causally linked to action selection rather than merely correlated with it. And it was evaluated on two open models, Pi0 and OpenVLA, both in the LIBERO simulation benchmark and on a physical UR5 arm, so this is not a result that only exists in a simulator. The Physical AI Safety Institute, which Häon co-founded with Stocking, now a research assistant professor at the Toyota Technological Institute at Chicago, describes the work as the first interpretable control interface for vision-language-action models. Häon says on Root Access that roughly 30 pieces of work have built on it since, moving on to sparse autoencoders and world action models.
For a founder the implication is narrow and concrete. Behavior in a robot foundation model is not only addressable through the prompt and the fine-tune. There is a third surface, inside the model, that can be moved at runtime without a training cycle. Whether you can reach that surface depends entirely on what your model vendor exposes, which makes it a procurement question rather than a research one. It is the robotics version of the rule that you should build for the next model rather than marry the one you started on.
Reliability and safety are the same engineering surface
It is easy to file safety under compliance, somewhere behind shipping. That reflex is worth examining here, because in this field the word covers a spectrum rather than one concern. Häon puts the range plainly. People arrive at AI safety from positions, in his words, "Anywhere from we just want our systems to be more reliable to there could be serious catastrophic risk here."
Both ends run on the same mechanism. His argument is that once you have "a general reasoning model that is operating on probability distributions of what anything really semantically means in the real world", you have added a surface of risk that amplifies what the AI safety community was already worried about. A long-horizon task can drift. The model may have improved without you being sure its internal objective still matches the one you wanted. His sharper illustration is the gap that closes when a model gets a body: knowing how something dangerous is done and being able to carry it out stop being separate problems.
You do not have to accept the catastrophic end of that range to use the engineering that comes with it. The workshop's call for papers names the risk directly: goal misgeneralization, jailbreaks, and specification gaming are failure modes the language model world has studied for years, and the call's argument is that each can become a physical harm when the model controls a robot. That is the same discipline that turns AI reliability from a slogan into a measured property, applied to a machine that can hurt someone.
The research streams the institute runs its fellowship on are the most useful taxonomy I have found for this, and they read like a founder's risk register. They run across mechanistic interpretability, adversarial robustness covering jailbreaking and prompt injection in the embodied action space, runtime monitoring to detect when a policy is operating outside its competence, sim-to-real transfer of safety behaviors, and security proper: attack vectors, data poisoning, and the supply chain for deployed robot models.
Read those last two as a security person would. Prompt injection in an embodied action space means that a label on a box, a sign on a wall, or a sticker someone places in your warehouse is an untrusted input to a system with a motor. Supply chain for deployed robot models means the weights you pulled, the fine-tune a contractor ran, and the update channel that pushes a new policy to machines already on a customer site. If your threat model covers the first category and not the second, you are in the majority, and that is the gap to close.
The three questions the field has not settled
The workshop Häon helps organize exists because, as the organizers put it, the two communities best equipped to address this rarely meet: safety research seldom touches physical hardware, and robot learning seldom engages frontier interpretability and alignment. The Science of Physical AI Safety runs at the 2026 Conference on Robot Learning on November 12 in Austin, with speakers including Marco Pavone of Stanford and Nvidia, Andrea Bajcsy of Carnegie Mellon, Vikas Sindhwani of Google DeepMind, and Thomas Fel of Goodfire and Harvard. Its call drew 121 submissions and is now closed.
It is organized around three open questions, and those three questions are the most useful diligence frame available to a founder buying a model:
- What transfers from AI safety. Which interpretability, alignment, or control technique developed for language models has actually been run against this robot model, and what did it show.
- What carries over from classical robotics. Which guarantees from kinematics, dynamics, and control still hold when a learned policy is in the loop, and which ones quietly stopped applying.
- How to evaluate at all. Whether judging a robot foundation model needs methods neither discipline currently has, which is a polite way of saying nobody should accept a benchmark number as evidence of fitness.
A field that is still deciding its evaluation methodology is not a reason to stay out. It is a reason to write your own acceptance criteria rather than inherit someone else's.
What to demand of the model underneath
Translate the above into the questions you put to whoever sells you the model, before the pilot and in writing.
- A steering interface, not just a prompt. Ask what internal control the model exposes, and whether behavior can be modulated at inference without a retrain. If the honest answer is that the prompt is the only knob, you are buying a black box and should price the risk accordingly.
- Named semantic directions, with causal evidence. The Berkeley work identified directions like speed and direction and showed they were causally linked to action selection. Ask which directions have been identified in the model you are buying, and what evidence separates causation from correlation.
- The envelope the vendor assumes you have. Every model ships with an implicit assumption about what the surrounding system will refuse to execute. Get that assumption stated. A vendor who has never been asked the question is telling you something.
- A competence signal. Ask how the model indicates it is operating outside what it has seen, and what your system is supposed to do with that signal. Runtime monitoring is a named research problem, one the Physical AI Safety Institute runs a fellowship stream on, precisely because a policy operating outside its competence does not announce it.
- The security posture of the model supply chain. Who can push a policy update to a deployed fleet, how is that artifact signed, and what is the rollback path. Treat the action stream and the update channel as the two highest-value targets in the product, because they are.
- An evaluation you own. This one is the easiest to defer and the most expensive to skip, and the sharpest statement of it comes from the most mature deployment of physical AI rather than from robot foundation model research. Waymo co-CEO Dmitri Dolgov, speaking on YC's channel, argues that the model is table stakes while the evaluation is the real advantage: "build your eval before you build your technology". His test is the one to carry into a vendor meeting: "If you can't quantitatively define what good enough means, you're not really building a product, you're just iterating on your demo."
None of these require you to run an interpretability team. They require you to treat the model as a component with a specification, which is how you would already treat a motor controller.
What to do this week
- Write down the five behaviors your robot must never produce, in physical terms rather than prompt terms, and decide which system enforces each one.
- Send your model vendor the six questions above, in writing, and keep the answers with the contract.
- Build one acceptance test you own, on your own task, that returns a number. Run it against the model you have today so you have a baseline before you upgrade.
- Add the embodied action space to your threat model: untrusted inputs the robot can see, the action stream itself, and the policy update channel.
- Read the Berkeley steering paper with an engineer rather than alone. The method is a short read with real content, and it will change what you ask for.
Robotics companies that treat the model as an opaque dependency will spend the next two years unable to explain their own product to a buyer who asks a good question. The teams that learn to inspect and steer what they bought will ship into regulated environments sooner, and that gap is an operating choice available now. If you want the broader version of that discipline across product, engineering, and go to market, start with the AI for startups pillar, then put it to work in the AI Operating System for Startups.
Sources
- Interpretability and Safety for Robot Foundation Models (YC Root Access), the interview this article distills, with Bear Häon on applying AI safety techniques to systems that think and physically act.
- Mechanistic Interpretability for Steering Vision-Language-Action Models, by Bear Häon, Kaylene Stocking, Ian Chuang, and Claire Tomlin, Conference on Robot Learning 2025, for the method, the semantic directions, and the Pi0, OpenVLA, LIBERO, and UR5 evaluation.
- Physical AI Safety Institute, co-founded by Häon and Stocking, for the research agenda and for the description of the paper as the first interpretable control interface for vision-language-action models.
- The Science of Physical AI Safety and its call for papers, for the workshop's three open questions, date, speakers, and submission count.
- Profiles: Bear Häon, Kaylene Stocking, and Claire Tomlin.
- Waymo Co-CEO Dmitri Dolgov: The Demo Is Only 1% Of The Work (Y Combinator), for the argument that evaluation rather than the model is the strategic advantage. Dolgov's role: Waymo.
Frequently asked questions
What is a robot foundation model?
A robot foundation model is a single pretrained model that accepts an open-ended instruction in natural language, takes in what the robot's sensors observe, and outputs the actions that move the machine. It replaces the modular pipeline robotics used for decades, in which perception, planning, and control were separate systems grounded in explicit models of kinematics, dynamics, and control, and each machine was tuned by hand for one task. Two families get named most often: vision-language-action models, which start from a pretrained vision-language model and learn to emit actions, and world action models, which predict how the world changes under an action and act through that prediction. The practical difference from a traditional robot policy is that you adapt a broadly pretrained model rather than build one from zero, which is why the model layer in robotics has become something a startup buys instead of something it spends years creating.
Can you steer a robot foundation model without retraining it?
Yes, and that is the finding behind the first framework for interpreting and steering these models through their internal representations. In Mechanistic Interpretability for Steering Vision-Language-Action Models, presented at the 2025 Conference on Robot Learning by Bear Häon, Kaylene Stocking, Ian Chuang, and Claire Tomlin, the feed-forward activations inside the transformer layers are projected onto the model's own token embedding basis, which yields a readable map of the concepts each block responds to. Those blocks can be clustered by concept and amplified during the forward pass, which moves behavior while the natural language command stays identical. The steering happens at inference with no fine-tuning, no reward signal, and no environment interaction, and it was demonstrated on two open models, Pi0 and OpenVLA, in the LIBERO simulation benchmark and on a physical UR5 arm. Whether you can use this on a model you buy depends on what internal access the vendor exposes.
How do you evaluate a robot foundation model?
Carefully, and with a test you wrote yourself, because the field has not settled the question. The Science of Physical AI Safety workshop at the 2026 Conference on Robot Learning is organized around three unsettled questions, and the third is whether evaluating robot foundation models demands methods that neither AI safety nor classical robotics currently provides. In that situation a vendor benchmark is a marketing artifact rather than evidence of fitness for your task. The practical approach is the one Waymo co-CEO Dmitri Dolgov argues for, that your model is table stakes while your eval and metrics are the strategic moat, so you build the eval before you build the technology. Carried into a robotics pilot that means an acceptance test on your own task that returns a number you can track across model versions. His test is a good filter for any robotics pilot, that if you cannot quantitatively define what good enough means, you are iterating on a demo rather than building a product.
Is a robot foundation model riskier than a language model?
It carries the same failure modes plus a physical consequence, which is the argument the physical AI safety field is built on. Robot foundation models inherit the transformer and diffusion substrates that AI safety research has spent years dissecting, so goal misgeneralization, jailbreaks, and specification gaming may transfer along with the architecture, and each one can become a physical harm when the model drives a machine. Bear Häon, who co-founded the Physical AI Safety Institute with Kaylene Stocking, describes a general reasoning model acting on probability distributions about what things mean in the real world as an added surface of risk that amplifies the concerns the AI safety community already had. Two risks deserve specific attention from founders because they are underpriced: prompt injection in an embodied action space, where a sign or a label becomes an untrusted input to a system with a motor, and the supply chain for deployed robot models, meaning who can push a policy update to machines already on a customer site.
Build your AI Operating System
A practical course to grow with AI, build internal tools, and operate safely. Join the waitlist and you'll be first in when the course opens.