Enterprise AI Adoption Is a Workflow Problem
Cicero Campelo, CISSP
October 17, 2026 · 19 min read
Part of our guide to AI for startups.
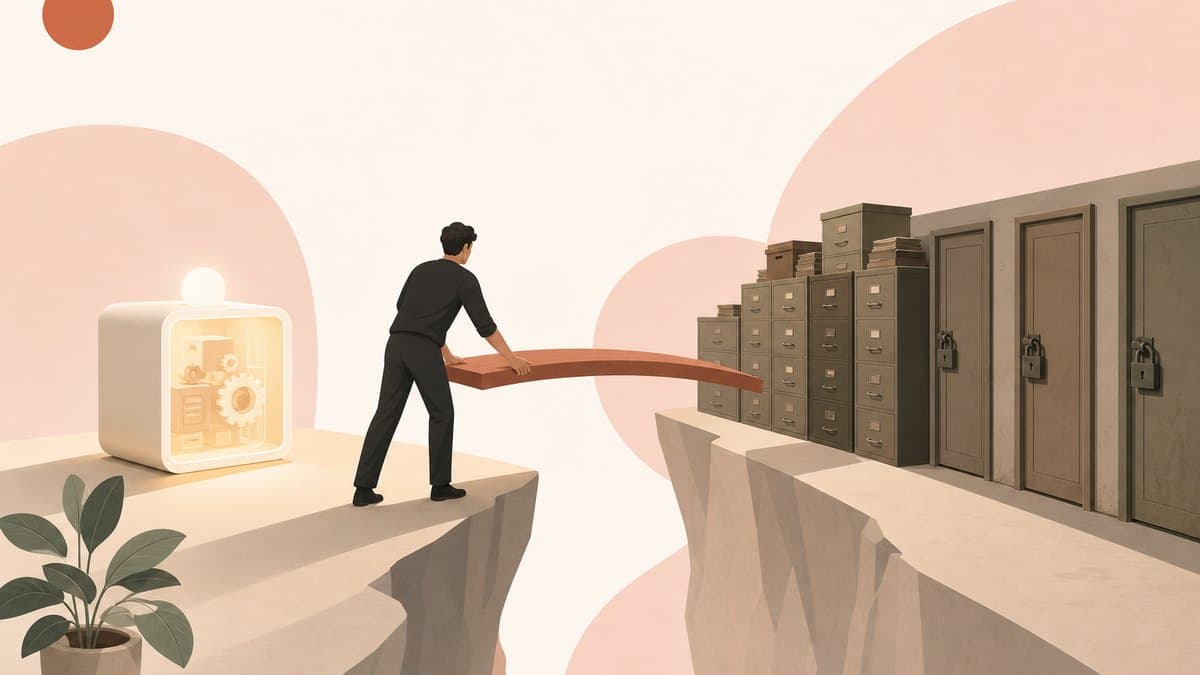
Table of contents
- What enterprise AI adoption actually means
- The gap is between the model and the workflow
- Why coding diffused first, and the likeness test it gives you
- There is no "give us your GitHub" for knowledge work
- The accuracy number that decides whether a workflow gets automated
- Chatbots do not fit the shape of enterprise work
- Permissions are the adoption bottleneck nobody demos
- The trust tax that slows adoption inside the company
- If you sell software, the mandate is two-sided
- What to do this week
- Sources
- Frequently asked questions
Over the course of 2026, coding agents went from novelty to default. Everything else in the enterprise is still crawling. That asymmetry is the single most useful fact about enterprise AI adoption right now, because the reason for it is not model quality. It is that a model has to land inside a workflow, and most workflows were not built for a participant that has no login, no manager, and no patience.
Aaron Levie, co-founder and CEO of Box, has an unusual vantage point on this. Box sits on a very large pile of enterprise files and has bet the company on agents that can read them, which makes him both a vendor of AI and a buyer of it. Talking to Sonya Huang, a partner at Sequoia, on the firm's Training Data podcast, he made an argument most AI commentary skips: the slowness is not a bug in the technology, it is the shape of the opportunity.
"Silicon Valley has to prepare for diffusion taking a lot longer than they think," he said near the end of the conversation. Earlier in it he had put the flip side of that point, which is the part founders should write down: "the diffusion kind of economy is going to be massive."
What enterprise AI adoption actually means
Enterprise AI adoption is the point at which a model is doing real work inside a company's existing business process, not the point at which the company has bought licenses or run a pilot. The difference matters because the two are measured by completely different things. Licenses are measured by seats and spend. Adoption is measured by whether a specific workflow now runs end to end at an accuracy the business will accept, with the data access, approvals, and exception handling solved.
Almost every "AI adoption" number you see in the market measures the first thing. That is why the surveys look encouraging and the companies look stuck. A sales team with a chatbot has bought AI. A bank whose client onboarding completes in an hour instead of two weeks has adopted it.
This is the layer where most of the work lives, and it is not research work. Levie's list of what still has to happen after the model is good enough reads like a project plan, not a paper: "that workflow still requires you to connect up to other data systems," there are moments where a human has to review something and the agent sits idle, and then the two that quietly eat quarters, "there's change management of the actual business process. There's legacy systems that haven't been modernized."
The gap is between the model and the workflow
The framing Levie uses is a bridge. "What you need is some bridge from the models capability to the actual workflow that the enterprise has," he said, and roughly a trillion dollars of investment has been placed on one of two answers about that bridge: it is narrow and the model providers will absorb it, or it is vast and it is a software industry of its own.
His analogy for why the second answer keeps winning is worth sitting with. A decade ago, looking at what the cloud providers were building in data infrastructure, almost nobody would have predicted Snowflake and Databricks. The infrastructure appeared to already do the job. It did not, because the job was never storage and compute, it was making a company's data usable by the people who had questions about it. Levie expects intelligence to rhyme: the models will be enormously valuable, and the software that carries those models into banking, life sciences, healthcare, and government will also be enormously valuable, for the same reason.
For a founder, the useful part is that this gap is specifiable. Every blocker on his list is a thing you can go look at in a prospect's building:
- The data is in a system the agent cannot reach, or can reach only with credentials nobody wants to issue.
- The process has a human checkpoint, so the agent has to be able to pause, hand off, and resume without losing state.
- The business process itself has to change, which means someone has to persuade a department to work differently.
- The surrounding systems are old enough that they have no API worth the name.
None of that is glamorous and all of it is billable. Levie is blunt about who ends up doing it. Unless you believe the labs will themselves hire on the order of a hundred thousand people to go do this work, every company that adopts it, from a 50 person firm to the largest enterprises, "is going to need an army of people to go in and help them with that transformation, that change management." If you have ever wondered why the forward deployed engineer line item keeps showing up in AI company budgets, that is the answer.
Why coding diffused first, and the likeness test it gives you
Coding did not diffuse first because engineers are early adopters. It diffused first because code has a set of properties almost no other knowledge work has, and once you can name them you can score any workflow for how fast AI will land in it.
Levie's first property is the one that does the most work: "the utility of code is almost 100% represented by the amount of text that you can generate." Enormous amounts of judgment and context go into software, but the output is text, and the text is the thing that produces the value. "For most of the world, code is a utility." Nobody minds that it was generated, because generating it was the bottleneck.
Then stack the rest: the labs treat coding as a competitive benchmark and improve it daily, they dogfood it because they write the models in it, the audience is technical enough to debug its own agent failures instead of filing a ticket, and the hourly cost of the people doing the work is high enough that even a small productivity gain pays. Five or six properties, all pointing the same direction.
Now run the test on something else. Legal scores well: a lot of value is created by a person at a computer reading, drafting, and processing large volumes of documents. A sales rep scores badly, and Levie's description of why is the clearest statement of the limit I have heard. "The sales rep's value creation is basically convincing an external customer to buy software or technology or a caterpillar truck." Bring the world's best automation to that job and the rep is still gated on whether the customer replied, whether they can meet Tuesday, and whether they have budget. The work is rate limited by other people.
Levie says he has not seen anyone publish that histogram. Here is a workable version of it. Before you build, score your target workflow on five questions:
- How much of the value is text or structured output the model can produce directly?
- Can the person doing the work fix the agent when it breaks, or do they need help?
- Is the output measurable against a benchmark, or is quality a matter of taste?
- Is the work gated on external parties who move at their own speed?
- Is the hourly cost of the current labor high enough that a partial win pays?
A workflow that scores well on four of five is a product. A workflow that scores well on one is a services business pretending to be a product, and you should price it accordingly. This is the same discipline as defining the ideal customer profile you are willing to serve deeply, applied one level down to the task.
There is no "give us your GitHub" for knowledge work
Here is the structural advantage of coding that almost nobody accounts for. When coding agents launched, onboarding was one step. The code was already in GitHub, so connecting to GitHub was the whole integration. As Levie describes that period, "there was no like sign up or register it was just like give us your GitHub." There was no data migration, no integration project, no mapping exercise. The corpus was already in a single, API-addressable, standardized place.
"There's no like give us your GitHub for knowledge work." Enterprise knowledge sits in on-premises systems, legacy file shares, and environments that were never designed to talk to an agent. Levie makes the point against his own interest, which is why it is credible: Box customers have an easier time of this, and he immediately notes that Box is "only 1.3 billion in revenue run rate," so most of the world's enterprise content is somewhere else. Box's most recent reported quarter at the time, the second of fiscal 2027, was $321.1 million in revenue, which annualizes to about $1.28 billion, and the company has guided the full fiscal year to approximately $1.29 billion. His round number is a fair description of the current run rate, and the conclusion holds either way: the addressable mess is far larger than the part already in a modern system.
Then there is the access problem, which he says he had almost forgotten about because it is so taken for granted in software. "In coding, you get access to basically most of the stuff ever relevant for your job." In knowledge work you do not. Permissions are scoped per project, per matter, per client, and they change daily. "How do you make sure the agent has access to those set of things?"
That question is where most enterprise AI pilots actually die, and it never appears in the demo.
The accuracy number that decides whether a workflow gets automated
Founders selling into enterprises tend to argue about model choice. Buyers argue about a number. Levie gives the shape of it with a loan processing example: on hundred-page documents, "whether you're getting 70% accuracy with an off-the-shelf model or like 97% is like basically obviously a world of difference in can you actually go and automate that process."
That is the whole sale. Below the threshold, a human still reviews everything and the workflow has not been automated, it has been annotated. Above it, the process changes shape. And the threshold is set by the cost of a mistake in that specific process, not by a leaderboard.
Which is why the serious buyers show up with their own evals. Levie describes customers saying, in effect, "I want to really make sure that at this cost profile I can get 98% accuracy on data extraction," and then testing several models against their own data with help from someone whose job is to get them there. The procurement conversation has become an engineering conversation.
Three things follow for a founder:
- Your harness is the product, not the model. Box built an agentic harness that knows its own file system, permissions, and search behavior, with tools for pulling text, chunking documents, and embedding on the fly. Levie says it measurably beats handing a frontier provider raw API access on both accuracy and latency, because it is tuned for the workflows. The gap between those two is your margin.
- Publish an eval your buyer recognizes. Levie says Box runs two evals: one of domain-specific document work across life sciences, financial services, the public sector and tech, among others, and a holdback eval on how Box employees use their own data. That is a sales asset as much as an engineering one. If you need the mechanics, start with LLM evals for founders.
- Expect mature workflows to migrate down the cost curve. Levie points at Jesse Zhang, co-founder and CEO of Decagon, whose argument is that frontier labs keep owning discovery while open models increasingly own production: once a use case's inputs, failure modes, and evaluation criteria are understood, a fine-tuned smaller model can hold the quality and latency bar. Levie adds the commercial half of it, which is that you move when the smaller model is either literally cheaper or post-training buys you real accuracy. On open-weight adoption in his own customer base, Levie's read is "probably higher than people think, lower than what enterprises actually want," and much lower than it will be. Plan your inference cost curve for that migration instead of being surprised by it.
Chatbots do not fit the shape of enterprise work
The chat box is permanent. It is also the wrong primary interface for most of what an enterprise does, and Levie's reasoning is a product lesson rather than a UI preference.
A chatbot serves a one-off ask: find this, answer that, draft this. But the enterprise is mostly made of processes that run quietly, some by computers, some by people, and some that should happen but were never affordable enough to staff. For those, you want an agent working in the background to "read every contract, look at every log, triage every security incident," and then you want to see the results in a form you can act on. His list of what that form is deserves to be read out loud at your next design review: "I want a dashboard. I want a workflow. I want a queue. I want a task list."
Chat is how you catch up on that work, not how you request it.
This is also where he makes his sharpest prediction, and it is a prediction rather than a measurement: "in five years from now I would bet like 90% of all tokens in the enterprise are things that a user never kicked off and they just see a result." If that is even directionally right, it reorders a product roadmap. The surface that matters is not the prompt box, it is the review queue: how a human sees what the agent did, judges it quickly, and corrects it. Teams that have thought hard about proactive AI are already building toward that, and the design problem it creates is trust in the output rather than access to the model.
Permissions are the adoption bottleneck nobody demos
This is the section a security person would write, and it is the one that decides whether the deal closes.
Levie's example is a law firm, and it kills a lot of fashionable architecture. A researcher imagines the world works the way their own does: full access to everything, so a model trained on your whole world would be wonderful. Then meet a lawyer, who can see the five matters they are staffed on and nothing else, because one door over a colleague is working for a competing company in the same space, and nothing may cross between them. "There can't be a single document that passes between those two walls and they have to be these kind of hard barriers."
Now add the part that breaks the architecture rather than just constraining it: that lawyer's access changes every day. People get added to matters and removed from them. Any design that bakes a user's context into weights has to answer what happens when the context they are allowed to see shrinks on Tuesday. Retrieval can enforce a permission check at query time. Weights cannot un-learn a document because a conflict was declared. That is not an argument against continual learning, which Levie is openly a fan of, it is the reason the enterprise version of it is harder than the demo version, and why the practical question is which knowledge is stable enough to bake in and which has to stay in a lookup path. Context engineering for AI agents is the discipline that answers it, and agent identity is where the permission check has to live.
Two rules fall out of this for anyone building agents for regulated buyers:
- Model the permission boundary before you write the prompt. An agent that can answer a question it should not have been able to answer is not a bug you patch later, it is a disclosure. Design the retrieval path so every document the agent reads was checked against the acting user's current entitlements, at read time, not at index time.
- Accept the productivity discount and sell it. Levie is candid that Box will not drop practices like code review to go faster, because "our customers can't possibly entrust us with their data security and compliance if we don't take that seriously," which means "we're always going to have a little bit of a discount on the productivity." If you sell to banks, hospitals, or governments, that discount is not a weakness to hide. It is the thing the buyer is paying for.
The trust tax that slows adoption inside the company
There is one more drag on adoption that has nothing to do with infrastructure: people have started discounting work they suspect a model wrote.
The research has a name for the artifact. Researchers at BetterUp Labs and Stanford's Social Media Lab called it workslop in a September 2025 Harvard Business Review article, defining it as AI-generated content that looks like good work but lacks the substance to move the task forward, so the real work transfers to whoever receives it. In their survey of 1,150 full-time US desk workers, 40 percent said they had received workslop from a colleague in the previous month.
Levie's explanation of why we accept generated code and flinch at a generated deck is the sharpest version of this I have read. A document is a proxy for its author's judgment. "When you get a presentation from somebody, there's still this association which is like I'm trying to decide if I can trust that person to go and execute on that thing." Code carries no such signal. Nobody reads a working backend and wonders whether the engineer understood it. So the same tool that is obviously welcome in one domain reads as evasion in another, and he thinks society spends the next few years working out what a document is now supposed to prove.
For a founder shipping an AI product into a company, that is a design constraint, not a cultural observation. If your agent produces something a human will put their name on, you have to give them a cheap way to verify it: the source passage, the confidence, the diff against what was there before. Adoption inside an organization moves at the speed of the reviewer's willingness to sign.
If you sell software, the mandate is two-sided
Levie's advice to anyone running a system of record is to do two things and to understand that doing only one loses.
The first: "you have to build an agent that is insanely great at your product." Not by hobbling anyone else, but by being so tuned to your own data model, permissions, and workflows that you can prove a double-digit accuracy advantage over a general-purpose agent operating on your APIs. You earn that with domain knowledge your customers hand you every week, including use cases nobody has built a product for yet. His example is a background agent that watches for documents drifting out of a governance policy and flags it before the employee acts, which sounds mundane until you remember that every large company has a head of governance who has never been able to be everywhere at once.
The second is the one incumbents resist: "you have to go headless. You literally have to make sure that your APIs are exposed" to the assistants your customers already use, through MCP or deterministic APIs, so an outside agent can drive your system. The fear is cannibalization. The evidence runs the other way. Levie's own usage is the anecdote: "I use Salesforce more today, probably by an order of magnitude than I ever have because I MCP into it." Make yourself reachable and consumption goes up, which is why the commercial model on that side has to be volume-oriented rather than seat-based. The same logic applies to how you present your own product to agents, which is the argument in LLM SEO and in agent experience.
He closes on the mandate, and it is a correction to the instinct most technical founders have. In a world where AI builds things far faster, he said, "whoever can actually get it to the customer is in the best position." Then the sentence to tape to the wall: "there is quite literally trillion to trillions up for grab at the applied layer." The constraint is no longer building the thing. It is getting it installed, trusted, and permissioned inside a company that has other priorities.
That is also the honest reason the diffusion gap is good news for a startup. If adoption were easy, the labs would have taken it. It is not, so it is yours, as long as you build for the gap rather than complaining about it. The wider view of that strategy sits in AI for startups, and the company-level version of the same work, told from inside one business that rebuilt itself around agents, is in AI transformation.
What to do this week
- Score one target workflow on the likeness test. Run the five questions above against the single workflow you most want to sell into. Write the score down. If it fails on external rate limits or on taste-based quality, you have found why your pilots stall.
- Ask your next three prospects where the data lives. Not whether they are interested in AI. Which system, whose credentials, and who can issue them. The answer predicts your implementation cost better than any other question in the first call.
- Get the accuracy threshold in writing. Ask the buyer what accuracy, at what cost per document or per task, would let them stop having a human review every output. That number is your spec. Without it you are negotiating against a feeling.
- Map the permission boundary before you build the retrieval path. List the walls that must hold inside the customer: matters, clients, regions, clearances. Then design so every read is checked against the acting user's current entitlements.
- Pick one headless surface and ship it. Expose the part of your product an outside agent would most want to drive, through MCP or a clean API, and measure whether usage rises. Levie's bet is that it does.
- Add a verification affordance to one AI output. Source passage, confidence, or a diff. If a human has to sign their name to what your agent produced, make signing cheap.
If you want the full operating system for this, the course walks through building the product, the evals, the permission model, and the go-to-market around it: AI Operating System for Startups.
Sources
- Box's Aaron Levie: On Reinventing Yourself in the AI Age and Enterprise Diffusion, Sequoia Capital's Training Data podcast with Sonya Huang. The interview this article distills, and the source of every Levie quote above.
- Box financials: Box's fourth quarter and fiscal 2026 results and second quarter fiscal 2027 results, for the revenue figures that put his run-rate comment in context. Leadership: Box.
- Workslop: "AI-Generated Workslop Is Destroying Productivity" in Harvard Business Review, by researchers at BetterUp Labs and Stanford's Social Media Lab, with the survey detail also carried by BetterUp's own research page and TechCrunch.
- Open models and use-case maturity: "Everyone is wrong about open source AI in the enterprise" by Jesse Zhang, co-founder and CEO of Decagon, the post Levie cites.
Frequently asked questions
What is enterprise AI adoption?
Enterprise AI adoption is the point at which a model is doing real work inside a company's existing business process, not the point at which the company has bought licenses or run a pilot. The two are measured by completely different things: licenses are counted in seats and spend, while adoption is measured by whether one specific workflow now runs end to end at an accuracy the business will accept, with data access, approvals and exception handling solved. That distinction explains why adoption surveys look encouraging while the companies behind them look stuck. Aaron Levie, co-founder and CEO of Box, frames the remaining work as a bridge from what the model can do to what the workflow actually needs, and his list of what sits on that bridge is operational rather than scientific: connecting to other data systems, handling the moments where a human has to review something and the agent waits, changing the business process itself, and dealing with legacy systems that were never modernized. A sales team with a chatbot has bought AI. A bank whose client onboarding completes in an hour instead of two weeks has adopted it.
Why is enterprise AI adoption so slow outside of coding?
Because coding has a stack of properties almost no other knowledge work shares, and the rest of the economy has to earn each one the hard way. The biggest is that the output is text: Levie puts it as the utility of code being almost entirely represented by the amount of text you can generate, so generating it was the bottleneck and nobody objects to automating it. On top of that, the labs treat coding as a competitive benchmark and improve it daily, they use it themselves, the users are technical enough to debug their own agent failures instead of filing a ticket, and the labor is expensive enough that even a small productivity gain pays. Onboarding was also a single step, because the corpus already lived in one API-addressable place. There is no equivalent for knowledge work: the data sits in on-premises systems and legacy file shares, and access is scoped per project or per client and changes daily. Levie's conclusion is that Silicon Valley should expect diffusion to take a lot longer than it thinks, and that the slowness is where the application layer's value comes from.
What is the biggest barrier to enterprise AI adoption?
Data access and permissions, not model quality. In software engineering a person generally has access to most of what is relevant to their job, so an agent inherits a usable scope by default. In the rest of the enterprise, entitlements are scoped per matter, per client, per region, and they change constantly. Levie's example is a law firm where a lawyer can see only the matters they are staffed on, because a colleague one door over is working for a competing company in the same space, and no single document may cross that wall. An agent has to respect the same boundary, enforced against the acting user's current entitlements at the moment it reads a document rather than at the moment the index was built. This is also the practical argument for keeping volatile knowledge in a retrieval path rather than baking it into model weights: retrieval can check a permission at query time, while weights cannot un-learn a document because a conflict was declared this morning. Levie is a fan of continual learning and still treats this as the reason the enterprise version of it is harder than the demo version. Most pilots die on this question, and it never appears in the demo.
How do you measure enterprise AI adoption?
Measure completed work, not usage. Three numbers tell you more than any dashboard of seats or tokens. First, the accuracy threshold per workflow: ask the buyer what accuracy, at what cost per task, would let them stop having a human review every output. Levie's loan-document example is the shape of it, where the difference between roughly 70 percent accuracy from an off-the-shelf model and roughly 97 percent decides whether the process can be automated at all, and serious buyers now arrive with their own evaluations rather than a model preference. Second, the share of work no human initiated: Levie predicts that within five years about 90 percent of enterprise tokens will come from tasks a user never kicked off, which makes background work rather than chat sessions the real adoption signal. Third, review throughput: how quickly a human can verify and sign off on what the agent produced. Adoption inside an organization moves at the speed of the reviewer's willingness to put their name on the output.
Build your AI Operating System
A practical course to grow with AI, build internal tools, and operate safely. Join the waitlist and you'll be first in when the course opens.