Hardware Software Co-Design: AI's Real 100x
Cicero Campelo, CISSP
October 7, 2026 · 12 min read
Part of our guide to AI for startups.
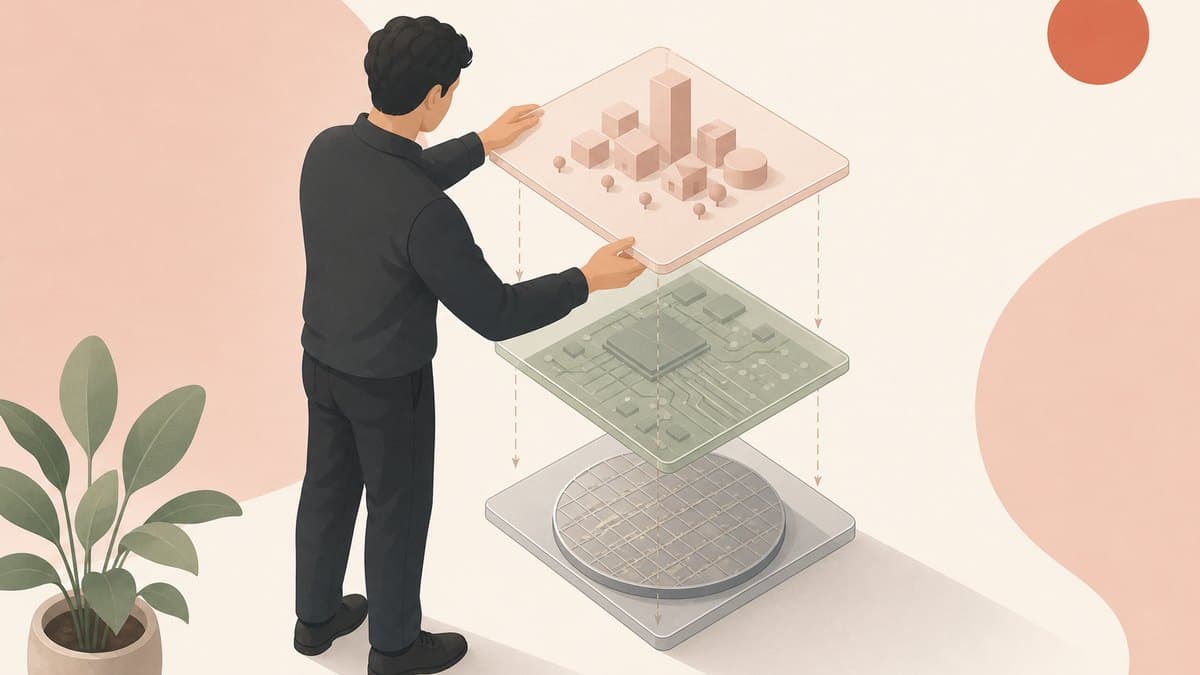
Table of contents
- What hardware software co-design actually means
- Which layer has actually been moving
- DeepSeek is the public worked example
- Which is why "GPU or TPU" is the wrong question
- What co-design looks like one layer down
- The moat moved, and it did not move where people say
- If you build above the model layer
- If you build below the model layer
- The security version of the same argument
- What to do this week
- Sources
- Frequently asked questions
Ask most founders where AI performance gains come from and you get one of three answers: better chips, better kernels, or better models. All three are real. None of them is the answer.
Hardware software co-design is the practice of tuning the model, the systems software underneath it, and the silicon it runs on as a single object rather than as three independent projects. It is why two deployments of the same quality model can differ by an order of magnitude in cost, and why a model that is excellent on one vendor's chip can be mediocre on another's.
Dylan Patel, founder and CEO of the semiconductor research firm SemiAnalysis, spent part of a long interview with Sequoia partners Shaun Maguire and Sonya Huang on exactly this. Asked which layer of the stack has produced the gains of the last three years, he disagreed with the premise of the question. The gains are in the seams.
What hardware software co-design actually means
Three layers sit between an idea and a token:
- The model layer. Architecture, sparsity, expert count and shape, the attention mechanism, how many parameters activate per token.
- The systems software layer. Kernels, collectives, schedulers, how bytes move between chips and how compute overlaps communication.
- The hardware layer. The size of the matrix multiply unit, memory bandwidth, the network topology, watts per square millimeter of silicon.
Optimizing any one of them is normal engineering. Co-design is choosing the model architecture because of what the chip is good at, and choosing the chip because of what the model needs. Patel names it plainly: "It's called software hardware co-design and that's what's like really exciting."
The arithmetic is the whole argument. Three layers each improving by 2x, worked separately, give you 8x. Worked together, the claim is that the same effort lands closer to 100x, because a choice in one layer opens headroom in the next that you could not have reached from inside that layer alone. We covered the single-company version of that bet in AI chip design, where the compounding loop runs inside one firm. This post is about the version that applies to everyone else.
Patel's summary of who does this well: "the beauty of the best labs is when they co-optimize all three."
Which layer has actually been moving
It helps to separate the three before arguing about the seams.
Hardware. From Nvidia's Hopper generation to Blackwell, Patel puts the gain at roughly 30x on the most optimized DeepSeek deployment over about three years. It is worth knowing where a number like that comes from: SemiAnalysis runs InferenceX, a benchmark that re-runs daily on current hardware and current models rather than testing once and publishing.
Models. Over the same window, the quality that required GPT-4 when it shipped in 2023 is now reachable, in his example, from a model with 27 billion total parameters and about 2 billion active. What all three layers moving at once does to a buyer is the number to internalize, and Patel reaches it from the whole stack rather than from the model layer alone: "model cost drop for equivalent quality by like 60x a year."
The layer between. Kernels, collectives and memory movement improved too, and Patel's read is that this layer has produced less of the headline gain on its own than the model layer has.
So if you stop there, the story is that models improved most. The interesting part is that he does not stop there: "a lot of this co-optimization is is the most important thing," and "it's it's hard to say you can disentangle the games." The layers are not additive contributors to one number. They are constraints on each other.
DeepSeek is the public worked example
Almost all serious co-design happens behind closed doors. DeepSeek is the exception, because the team published it.
DeepSeek-V3 is a mixture-of-experts model with 671 billion total parameters and 37 billion activated per token, trained on 14.8 trillion tokens across 2,048 Nvidia H800 GPUs. The technical report is not a model paper with a hardware appendix. It is a co-design document: FP8 accumulation promoted to higher precision on a fixed cadence to work around the chip's accumulation width, 20 streaming multiprocessors carved off and partitioned into channels dedicated to moving data, and custom PTX instructions plus a tuned communication chunk size, chosen together to hold down L2 cache use and interference with the compute units. The team later published a companion paper on the hardware implications for the 52nd International Symposium on Computer Architecture.
Patel's point about it is the one founders miss. Looking at the shapes of the experts in DeepSeek V3, he says, "they were all optimized for Hopper." The expert shapes are not a modeling choice that happens to run on a chip. They are a chip choice expressed in model geometry.
The consequence is uncomfortable if you believe hardware is fungible. Google's TPUs are, by any neutral measure, excellent silicon. Patel's assessment is still blunt: TPUs are bad at running DeepSeek, and "they are really really great at running other kinds of models that don't run well on NVIDIA."
Which is why "GPU or TPU" is the wrong question
The vendor comparison founders want to make cannot be made in the form they want to make it.
"How do you say that this is better than that when you can't measure them in isolation," Patel asks, "because it also extends up to the model layer." He is not dodging. The two architectures differ in ways that propagate upward into what model you would sensibly build:
- The matrix multiply unit is a different size, which changes the shape of the multiplies you want to do, which changes how you structure attention and how you structure experts.
- The network has a different shape. Nvidia connects GPUs through NVLink switches, and a single NVLink domain in the current rack-scale systems covers 72 GPUs. Google's inter-chip interconnect links each chip directly to its neighbours in a 3D torus that scales to 9,216 chips per pod, with an optical circuit switch network joining the cubes. Patel's framing of the trade-off is that there is no switch in the chip-to-chip path: "you have to pass through other chips to get there because there's no switch."
Neither is better in the abstract. Each is better for a model shaped to exploit it. His framing of where the frontier labs land: "I'll choose the best hardware and I'll co-design my model and infrastructure software through and through for that hardware."
What co-design looks like one layer down
This is not a boardroom abstraction. It is daily engineering, and the public literature shows the texture.
At a Y Combinator Paper Club session on multi-GPU kernels, Stuart Sul, a Stanford computer science PhD student and a researcher at Cursor who works on its Composer model, presented ParallelKittens, a framework for writing overlapped multi-GPU kernels. One of the three trade-offs he walks through is the transfer mechanism: the copy engine, tensor memory accelerator instructions, register instructions, and where each one falls over. On Blackwell, he reports, roughly 15 of 148 streaming multiprocessors are enough to saturate NVLink using one mechanism, while another mechanism keeps a capability the first one loses.
His line on that trade-off is the co-design principle stated small: "choosing the right transfer mechanism for the given workload really matters."
The framework is in production. Sul says Cursor uses it to train Composer on tens of thousands of Blackwell GPUs and that Together AI uses it for inference. That is the whole pattern in one example: a property of the workload drove a hardware primitive choice, and that choice is now load-bearing for a production training run.
The moat moved, and it did not move where people say
The received wisdom is that Nvidia's moat is CUDA, and that models writing their own kernels dissolves it. Patel half agrees: "models are just great at coding and all software gets commoditized in that case."
But he thinks the thing people call the CUDA moat was never really about CUDA. The open models everyone builds on, from DeepSeek and the Chinese labs and from Nvidia's own open releases, were co-designed for GPUs. Their expert shapes, hidden dimensions and attention structures assume that hardware. So when an inference provider or a fine-tuning company picks a chip, the decision is made for them upstream: "the downstream product is more optimized for Nvidia." Not because of the programming language, but because of the geometry of the weights.
That is a more durable kind of lock-in than an API, and it is worth understanding if you are reasoning about moats in AI at all. It also tells you what would break it, which is a serious open-weights ecosystem designed for a different chip.
If you build above the model layer
Most founders reading this are not training models. The co-design story still sets your constraints, in four specific ways.
Your co-design surface is real, it is just higher up. You co-design context, prompts, tool definitions, retrieval and evals against a model's actual behavior. The same rule applies: tuned together they compound, tuned separately they add. The practical version is in our AI for startups pillar.
Switchability is the hedge, and it has to be built. Harrison Chase, co-founder of LangChain, puts the model-layer version cleanly in a Sequoia talk: "You want to be able to switch to avoid lock-in, but also to just use the best model when it's available." He draws the analogy to being cloud agnostic back in the day. The analogy holds, including the part where agnosticism costs you performance and you pay it on purpose.
Do not architect around today's token price. Patel's 60x a year is an aggressive read, and even a conservative one of roughly 10x a year is enough to change your plan: a product that is uneconomic at current prices and a product that is uneconomic in principle look identical today and will not in eighteen months. That is a different calculation from the one in AI inference cost, which is about the bill you are paying now.
Your eval suite is your portability test. The only way to know whether a switch costs you quality is to have measured quality before the switch. Teams that cannot swap models usually cannot because they cannot tell whether the swap hurt.
If you build below the model layer
If you are building silicon, inference infrastructure or systems software, co-design changes the risk profile of the bet rather than the shape of the work.
Specializing is choosing a local minimum and hoping it is the global one. Patel's phrasing is that "some people will race to a local minima" and then face the problem of getting back out. A chip that is superb for the attention mechanism everyone uses in 2026 is a liability if that mechanism is replaced.
The labs do not know either. "They don't even know what architecture they're going to be doing in a year," he says of the frontier labs. They hold research bets, not plans. Any customer promise that requires them to know is a promise built on sand, which is why he still expects that "there will be a big market for general purpose AI compute."
The bottlenecks are legible, which is the opportunity. The two he names: memory capacity and bandwidth, where "capacity and bandwidth have been improving very slowly" and the interesting unlock is the one he describes as stacking "the memory directly on the chip and that makes your bandwidth explode"; and power density, where chips have sat near one watt per square millimeter for two decades and pushing past it would mean less silicon per unit of work.
The market is big enough to have edges. "Because the market has gotten so big, niches will be carved out," which is how a company that is not Nvidia or Google makes money anyway. The adjacent decisions are in inference chips and GPU clusters.
The security version of the same argument
Co-design and security pull in opposite directions, and it is better to know that going in.
Every layer you co-design is a layer you have coupled. A model tuned to one chip, served by a kernel stack tuned to that chip, is a single-vendor dependency with extra steps, and the dependency sits in a supply chain you do not control. Switchability is not only a commercial hedge. It is the control that keeps a vendor outage, a price change or an export restriction from being an outage of your product.
The honest counterweight is that portability has its own cost. Every additional inference provider you can fail over to is another processor of your customers' data, with its own retention terms and its own breach surface, and the abstraction layer you build to keep them interchangeable is code with privileges over every request you serve. Pick the number of providers you can actually diligence, write the fail-over down, and test it. Two that you have reviewed beats five that you have not.
What to do this week
- Write down which layer you can actually change. Model, serving stack, chip. For most teams the honest answer is one, and knowing which one stops you buying optimization you cannot use.
- Run your eval suite against a second model from a different family. Not to switch. To learn what switching would cost, while the answer is still cheap to find out.
- Price your product at one tenth of today's token cost and at three times it. If it only works at one of those, you have found the real assumption in your plan.
- Find the one place where your layers are tuned against each other, usually prompts against one model's quirks, and decide deliberately whether that coupling is worth the lock-in. Some of it is. Write down which.
- List every inference provider that touches customer data, including the one you added for a spike last quarter, and confirm each has a retention policy you have read.
If you want the full operating system for making these calls, from model choice through evals to the security posture around them, that is what the AI Operating System for Startups course is built to teach.
Sources
- Why Hardware-Software Co-Design Is AI's Real 100x (Sequoia Capital), Dylan Patel of SemiAnalysis with Sequoia partners Shaun Maguire and Sonya Huang, the interview this article distills. Dylan Patel's current role is confirmed on SemiAnalysis's own site.
- When to Build Your Own Agent Harness (Sequoia Capital), Harrison Chase of LangChain, for the model-switchability argument.
- Lessons From Training Composer At Cursor And Building Meta/Nvidia Compute Clusters (Y Combinator Paper Club), Stuart Sul's ParallelKittens talk, for the kernel-level view of co-design.
- DeepSeek-V3 architecture, parameter counts, training scale and the hardware-specific optimizations: the DeepSeek-V3 Technical Report and the team's follow-on paper Insights into DeepSeek-V3.
- ParallelKittens: the Hazy Research write-up from the Stanford lab that produced it, and Stuart Sul's own site.
- Interconnect scale: Nvidia's NVL72 reference architecture for the 72-GPU NVLink domain, and Google Cloud's TPU documentation for pod scale on its switchless interconnect.
Frequently asked questions
What is hardware software co-design?
Hardware software co-design is the practice of tuning a model, the systems software that runs it, and the silicon it runs on as a single object rather than as three independent projects. In AI that means choosing a model's architecture (its expert shapes, its attention mechanism, how many parameters activate per token) partly because of what a specific chip is fast at, and choosing or designing the chip partly because of what the model needs. Dylan Patel of SemiAnalysis calls it the most important source of efficiency gains in AI right now: "It's called software hardware co-design and that's what's like really exciting." DeepSeek-V3 is the clearest public example, because its technical report documents optimizations written down to the instruction level for the specific Nvidia GPUs it trained on.
Why does co-design produce bigger gains than optimizing one layer?
Because the layers constrain each other rather than contributing independently to one number. Three layers each improving by 2x, worked separately, multiply out to 8x. Patel's arithmetic is that worked together, where a choice in one layer opens headroom in the next that you could not have reached from inside that layer alone, the same engineering effort lands closer to 100x. His view is that the model layer has produced the largest single-layer gains of the last three years, but that the gains are genuinely entangled: "it's it's hard to say you can disentangle the games." His description of what separates the best labs is that they "co-optimize all three."
Does hardware software co-design matter if I am not training models?
Yes, but indirectly, and in two ways. First, it sets your costs: the price you pay per token is the output of co-design work done by somebody else, and Patel's figure for how fast that moves is a roughly 60x annual drop in model cost for equivalent quality, which means a product that is uneconomic today may not be in a year. Second, it explains where lock-in actually lives. It is not the programming language. Open models are shaped for the hardware they were co-designed on, so the chip decision is often made upstream of you. The practical response is to build switchability deliberately and to keep an eval suite good enough to tell you what a switch would cost.
Are TPUs better than GPUs for AI workloads?
The comparison cannot be made in that form, and Patel's answer is that asking it is the mistake: "how do you say that this is better than that when you can't measure them in isolation," because the comparison "also extends up to the model layer." The two architectures differ in the size of their matrix multiply units and in network topology, and a model is normally shaped to exploit one of them. His concrete example is that TPUs run DeepSeek badly while being "really really great at running other kinds of models that don't run well on NVIDIA." Whichever is better depends on the model you intend to run, which is the co-design point restated.
Build your AI Operating System
A practical course to grow with AI, build internal tools, and operate safely. Join the waitlist and you'll be first in when the course opens.